Llama 3.2 3B on a phone: RAM requirements
6GB-class phone runs it, tight · 4GB phones take the 1-bit doors
Llama 3.2 3B's recommended Q4_K_M build needs ~2.8 GiB of free RAM at 4K context — 1.9 GiB of measured weights plus a 0.44 GiB KV allowance and a 0.50 GiB runtime reserve. Count usable RAM at 60% of the sticker and the door for that build is a 6GB-class phone, tight; 12GB is the comfortable tier. A 4GB phone is genuinely in play — the 1-bit-class UD-IQ2_XXS build totals 1.9 GiB and fits with ~0.5 GiB to spare — and the LiteRT build (2.1 GiB) runs in Google AI Edge Gallery at the 6GB tier. Phones have no swap: past the line the app dies, it does not slow down.
unsloth Q4_K_M GGUF (1.9 GiB), keep context at 4K.Llama 3.2 3B is Meta's small open-weights instruct model (released 2024-09): 28 layers of GQA attention, 128K context, and a measured Q4_K_M file of 1.9 GiB — the smallest mainstream 3B with a tracked LiteRT build. The official meta-llama repo is license-gated, so the canonical bytes below come from the unsloth and bartowski GGUF mirrors (pinned, the same size for Q4_K_M in our listings) and the litert-community build.
Data verified · sources pinned in Where every number comes from
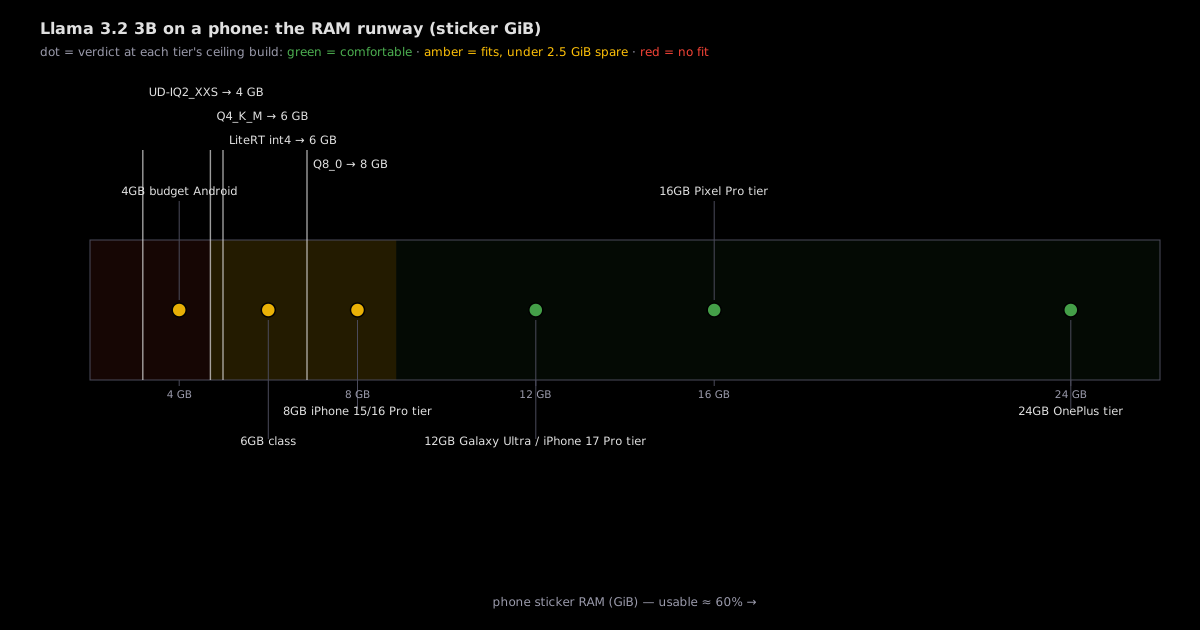
How much RAM at each build? (weights + 4K KV allowance + reserve)
| Build | Weights | Total needed | Smallest phone tier | Note |
|---|---|---|---|---|
| UD-IQ2_XXS | 1.0 GiB | 1.9 GiB | 4 GB tier | the 1-bit-class floor — the 4GB door measured |
| Q2_K | 1.3 GiB | 2.2 GiB | 4 GB tier | the smallest classic-quant door measured |
| Q4_K_M — recommended | 1.9 GiB | 2.8 GiB | 6 GB tier | Google AI Edge Gallery build — the 6GB door measured |
| LiteRT (mixed_int4 GPU) | 2.1 GiB | 3.0 GiB | 6 GB tier | community default quality/size point — recommended measured |
| Q5_K_M | 2.2 GiB | 3.1 GiB | 6 GB tier | the 8GB-class ceiling measured |
| Q8_0 | 3.2 GiB | 4.1 GiB | 8 GB tier | the quality ceiling for phones measured |
Caliber: this page counts in GiB throughout — the site-wide internal caliber — and applies the 60% usable rule to the sticker number as-is (4 → 2.4 GiB usable). Tier names keep the marketing GB spelling; every computed cell above derives from the pinned file bytes in provenance.
Is your phone enough? (find your phone class: one row tells you)
| Phone class | RAM | Usable | Biggest build that fits (ceiling) | Verdict |
|---|---|---|---|---|
| 4GB budget Android | 4 GiB | 2.4 GiB | Q2_K (2.2 GiB) | TIGHT · razor, ~0.2 GiB spare |
| 6GB class | 6 GiB | 3.6 GiB | Q5_K_M (3.1 GiB) | TIGHT · 0.5 GiB spare |
| 8GB — iPhone 15/16 Pro tier | 8 GiB | 4.8 GiB | Q8_0 (4.1 GiB) | TIGHT · 0.7 GiB spare |
| 12GB — Galaxy Ultra / iPhone 17 Pro tier | 12 GiB | 7.2 GiB | Q8_0 | OK · 3.1 GiB spare |
| 16GB — Pixel Pro tier | 16 GiB | 9.6 GiB | Q8_0 | OK · 5.5 GiB spare |
| 24GB — OnePlus flagship tier | 24 GiB | 14.4 GiB | Q8_0 | OK · 10.3 GiB spare |
Each phone class has exactly one ceiling — the biggest tracked build that fits. KV cache is counted at 4K context with a runtime reserve — phones have no swap, so there is no soft landing past the line. iPhone 15/16 Pro tiers sit at 8GB; the iPhone 17 Pro generation moved the Pro tier to 12GB (Sept 2025), and Android flagships carry the 12–24GiB end.
What phone should you buy for it? (the 6GB door logic)
| The logic | 6GB is the cheapest tier that runs the recommended Q4_K_M build at all (2.8 GiB total vs 3.6 GiB usable). Below it, 4GB phones run the 1-bit-class doors — razor-thin but real. Above it, 8GB stretches to Q8_0; 12GB is the comfort tier; 16GB is luxury for this model. |
| Why it fits | A 3.2B dense model keeps the measured Q4_K_M file at 1.9 GiB, so the whole 4K budget lands under 2.8 GiB — the 60% usable rule leaves real room where a 14B-class model never comes close. |
| Representative hardware | Moto G-class (4–6GB), Galaxy A-class (6GB), iPhone 15/16 Pro tier (8GB); 12GB = Galaxy S Ultra / iPhone 17 Pro tier; 16GB = Pixel Pro tier; 24GB = OnePlus flagship tier |
| Source | unsloth GGUF listing + litert-community listing · accessed 2026-09-16 · measured |
⚠ Tight is a site-wide threshold: under 2.5 GiB of headroom. 6GB × Q4_K_M leaves 0.8 GiB (tight); the comfortable Q4_K_M tier is 8GB (2.0 GiB spare) and 12GB (4.4 GiB spare). On iOS the binding constraint is often the absolute per-app cap, not the percentage.
Tracked builds (actual file sizes, not theory)
| Build | Publisher | File size | 8GB phone | 12GB phone | Source |
|---|---|---|---|---|---|
| Q4_K_M (recommended) | unsloth | 1.88 GiB | TIGHT · 2.8 | OK · 2.8 | HF @e7d0997e verified |
| Q4_K_M | bartowski | 1.88 GiB | TIGHT · 2.8 | OK · 2.8 | HF @5ab33fa9 verified |
Q4_K_M is the sweet spot, and here the publisher is not a size decision: unsloth and bartowski list the same 1.88 GiB file size (same size in our pinned listings; we compare sizes, not hashes — one build, two listings). The LiteRT build (2.1 GiB, table above) is the alternative runtime for Google AI Edge Gallery at the 6GB tier — it is the GPU-variant file, tuned for mobile accelerators. If you want the Gallery runtime instead of GGUF, that build fits 6GB phones tight.
How to run it on a phone
| iOS | PocketPal · LLM Farm |
| Android | PocketPal · llama.cpp (Termux or APK) · Google AI Edge Gallery (LiteRT) |
| Not MLC Chat | MLC Chat uses its own compiled model format and does not load GGUF files — for GGUF builds use PocketPal or llama.cpp. |
| Watch out | Thermal throttling cuts sustained tok/s on long generations; the OS reserve is why usable is 60%, not 100%; on iOS the per-app memory cap — not the percentage — is usually the binding constraint. |
Why phone RAM math is different
Phones have no swap: when memory runs out the app dies, not slows. In the community measurements we sampled, not one shows graceful degradation on a phone — iOS kills the app silently (jetsam), Android's LMK does the same; the boundary is a cliff, not a slope. KV cache shares one RAM pool with the OS and your background apps — that is why this page counts usable RAM at 60% of the sticker number. It is the same memory math as the GPU pages, with the budget switched from VRAM to unified phone RAM.
Running the same model on a desktop GPU is a different buying question — graphics-card VRAM, not the phone already in your pocket.
On thermals: short prompts feel instant almost everywhere the model fits. Sustained generation is where phones differ — a 2026 benchmark measured an iPhone 16 Pro dropping from ~40 tok/s peak to ~22.5 sustained over 20 iterations, and community reports put throttling onset at 30–60 seconds, so treat any speed number as a cold-start figure unless the source says otherwise (links in provenance).
The weights on this page are measured — GGUF and LiteRT file sizes read off the publishers' listings at pinned revisions (accessed 2026-09-16). What stays estimated is the total: KV cache at 4K context and a runtime reserve are added by simple arithmetic, and the KV figure is a classic-caliber upper bound derived from the pinned config, not a per-token measurement. The 0.60 usable rule stays an experience value — now with community measurements behind it — and if a better-supported figure shows up, the chart's zone boundaries move and the verdicts are recomputed.
Where every number comes from (every figure carries its tag)
Totals: labeled additive estimates — measured weights + KV allowance + runtime reserve.
| Tag | Slot | What it is | What the verdict can claim |
|---|---|---|---|
| measured | Weights | File sizes read off the publishers' Hugging Face listings at pinned revisions (accessed 2026-09-16): unsloth GGUF — UD-IQ2_XXS 0.98, Q2_K 1.27, Q4_K_M 1.88, Q5_K_M 2.16, Q8_0 3.19 GiB; litert-community — LiteRT mixed_int4 GPU 2.06 GiB (tree 401735124). Totals add a 4K KV allowance (0.44 GiB classic upper bound, from the pinned config: 8 KV heads × 128 dim × 28 layers) plus a 0.50 GiB runtime reserve. | Solid at file granularity — the weights are the files you will download; only the KV/reserve add-on is arithmetic. |
| reported | Usable = 60% rule | Experience value for the OS + background share, backed by community measurements: the maintained per-device table spans ~49–81% usable (per-device memory-budget table, accessed 2026-09-13), with a 2026 forums report of iPadOS 26.4 silently cutting 8GB iPads to ~37.5% (Apple Developer Forums 826325, accessed 2026-09-13 — single source, treated as provisional); iOS enforces a hard per-app cap rather than a percentage — PocketPal PR #651 measured 52% → 70% with the memory entitlement (accessed 2026-09-13). 0.60 is our conservative default inside that range. | Directionally safe — it separates 4GB phones from 12GB phones. On iOS the binding constraint is often the absolute per-app cap, not the percentage. |
| reported | App compatibility | PocketPal / LLM Farm / Google AI Edge Gallery (LiteRT) / llama.cpp — project pages, not re-tested by us on every device. MLC Chat uses its own compiled format and does not load GGUF files — listed here as a correction, not an option. | These apps load builds of this size class — stands on the linked pages, re-checkable by you. |
| reported | Thermal throttling 30–60% | Benchmarks + community measurements of sustained-generation slowdown on phone SoCs: iPhone 16 Pro measured ~40 → ~22.5 tok/s over 20 iterations (2026 thermal benchmark paper, accessed 2026-09-13; Apple-silicon LLM benchmark suite). | Expect slowdown on long generations — never a cold-start speed promise. |
| unsloth/Llama-3.2-3B-Instruct-GGUF | @e7d0997e | accessed 2026-10-12 |
| bartowski/Llama-3.2-3B-Instruct-GGUF | @5ab33fa9 | accessed 2026-10-12 |
| litert-community/Llama-3.2-3B | 401735124 | accessed 2026-09-16 |
| meta-llama/Llama-3.2-3B-Instruct (official, gated) | 0cb88a4f7 | metadata probed 2026-09-16 · files 403 |
| SO 5887248 · per-device memory budget table | latest | accessed 2026-09-13 |
| Apple Developer Forums 826325 · iPadOS 26.4 cap cut | latest | accessed 2026-09-13 |
| PocketPal PR #651 · entitlement 52%→70% | latest | accessed 2026-09-13 |
| zenn.dev · iOS memory entitlements measurement | 2026-06 | accessed 2026-09-13 |
| 2026 thermal benchmark paper (arXiv 2603.23640) | 2026-03 | accessed 2026-09-13 |
| john-rocky/apple-silicon-llm-bench | latest | accessed 2026-09-13 |
FAQ
Can Llama 3.2 3B run on a 4GB phone?
Yes — the 1-bit-class doors: UD-IQ2_XXS totals 1.9 GiB against 2.4 GiB usable, and Q2_K leaves ~0.2 GiB spare. Razor-thin but real, via PocketPal or llama.cpp. The recommended Q4_K_M wants a 6GB-class phone.
Is 6GB RAM enough for Llama 3.2 3B?
Enough for the recommended Q4_K_M build, tight: 2.8 GiB total against 3.6 GiB usable, 0.8 GiB to spare. Or take the LiteRT mixed_int4 GPU build (3.0 GiB) in Google AI Edge Gallery. 12GB is the comfortable tier.
Can Llama 3.2 3B run on Android?
Yes — GGUF builds load in PocketPal or llama.cpp, and the LiteRT build runs in Google AI Edge Gallery. There is no official Llama app; those three are the tracked paths. Cap context at 4K on phones.
Which Llama 3.2 3B build should I download?
For Google AI Edge Gallery, the LiteRT mixed_int4 GPU build (2.1 GiB). For PocketPal or llama.cpp, the Q4_K_M GGUF — unsloth and bartowski list 1.88 GiB files at the same size for this model, so either listing works.
What app runs Llama 3.2 3B on a phone?
PocketPal or llama.cpp for GGUF builds; Google AI Edge Gallery for the LiteRT build. MLC Chat uses its own compiled format and does not load GGUF. Cap context at 4K.