Qwen3-30B-A3B VRAM requirements
fits any 24GB card, tight — 1.7 GiB to spare · densest fit Q4_1 at 21.4 GiB, 1.1 to spare
Qwen3-30B-A3B needs 18.5 GiB at Q4_K_M (unsloth build) at 8K context and 20.8 GiB at 32K (reported KV counted) — any 24GB card runs it, tight, 1.7 GiB to spare. MoE does not shrink the footprint: all 30.5B parameters stay resident in VRAM; only 3.3B are active per token, which buys tok/s, not GB. The densest 24GB fit is Q4_1 at 21.4 GiB. Programming work? Its twin — the Qwen3-Coder-30B-A3B — measures the same 20.8 GiB (same weights, code-specialized training, 256K native context); the FAQ answers which one to download.
ollama run qwen3:30b — fits any 24GB card, tight at 32K (Ollama boots at 4K context — /set parameter num_ctx 32768 for the full window).Qwen3-30B-A3B is Alibaba's small MoE: 30.5B parameters, 3.3B active per token, 128 experts (8 active), 48 full-attention GQA layers (config.json: 32 query heads, 4 KV heads, head dim 128). VRAM follows total parameters, not active ones — every expert stays resident. KV cache at 32K is 3.0 GiB per kaitchup's measurement (98,304 bytes/token × 32K tokens, batch 1, bf16), reported and linked. Native context 32K; YaRN extends to 131K.
Data verified · sources pinned in Where every number comes from
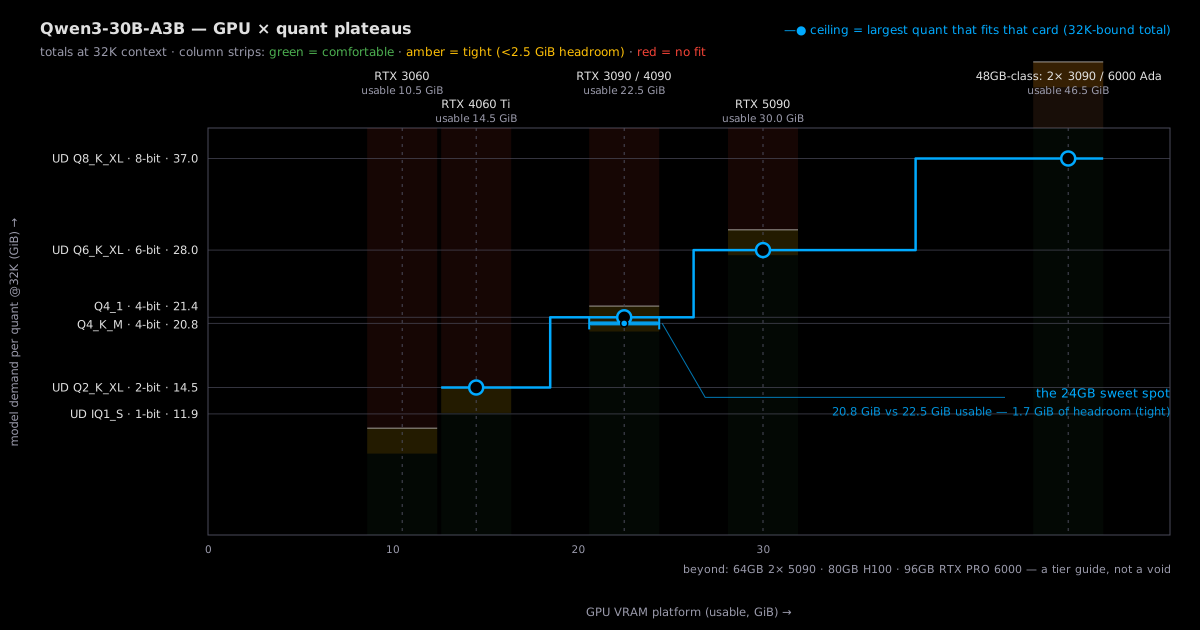
How much VRAM at each quantization? (weights + overhead + KV @32K, batch 1)
| Quantization | VRAM needed @32K | KV @32K reported i · already in the left column | Smallest tracked fit | Note |
|---|---|---|---|---|
| UD_IQ1_S | 11.9 GiB | 3 GiB | RTX 4060 Ti 16GB | measured · main column = the full 32K load |
| UD_Q2_K_XL | 14.5 GiB | 3 GiB | RTX 4060 Ti 16GB | measured · main column = the full 32K load |
| Q4_K_M | 20.8 GiB | 3 GiB | RTX 3090 24GB | measured · main column = the full 32K load |
| Q4_1 | 21.4 GiB | 3 GiB | RTX 3090 24GB | measured · main column = the full 32K load |
| UD_Q6_K_XL | 28.0 GiB | 3 GiB | RTX 5090 32GB | measured · main column = the full 32K load |
GB vs GiB: card names are the manufacturer's nominal GB; totals here are GiB (230 bytes) — a "24GB" card holds 24 GiB, and a file quoted 18,556,686,912 B in decimal is the same 17.3 GiB. Caliber →
The 48GB-class doors, spelled out: a dual-GPU combo (2× 24GB; not one card doubled), a workstation card (RTX 6000 Ada), or a Mac Studio (unified memory; runs, slower tok/s).
How this page computes the numbers (reproduce any cell)
- usable VRAM = nominal minus reserve, per card: 12GB → 10.5 GiB, 16GB → 14.5 GiB, 24GB → 22.5 GiB, 32GB → 30.0 GiB.
- total@32K = weights + overhead + KV@32K; KV@32K = 3 GiB (config-derived — 98,304 B/token effective at 32K; hybrid models carry a constant state on top, composition in sources).
- The main column already prices the full 32K load, KV included; shorter-context figures live in the caption and FAQ where relevant.
- A build fits a card at 32K when total@32K ≤ usable; tight = under 2.5 GiB of headroom, one site-wide threshold.
Is your GPU enough? (find your card: one row tells you)
| Your GPU | VRAM | Biggest quant that fits (ceiling) | How it feels |
|---|---|---|---|
| RTX 3060 12GB | 12 GB | — | — |
| RTX 4060 Ti 16GB | 16 GB | UD_Q2_K_XL (2-bit) · 14.5 GiB | 0.00 GiB spare at 32K |
| RTX 3090 24GB | 24 GB | Q4_1 (4-bit) · 21.4 GiB | 1.1 GiB spare at 32K |
| RTX 4090 24GB | 24 GB | Q4_1 (4-bit) · 21.4 GiB | 1.1 GiB spare at 32K |
| RTX 5090 32GB | 32 GB | UD_Q6_K_XL (6-bit) · 28.0 GiB | 2.0 GiB spare at 32K |
Quants stack by size: each GPU has exactly one ceiling — a card that runs a bigger build runs every smaller one. Main-column totals price the 32K load (weights + overhead + reported KV @32K); shorter context lowers every row by most of the KV term, and CPU offload trades tok/s for headroom.
What GPU should you buy for it? (the 24GB sweet spot logic)
| The logic | 24GB is the tier that runs Q4_K_M at 32K: 20.8 GiB with the reported KV counted, 1.7 GiB to spare — tight, but it holds. Below it, 16GB tops out at UD_Q2_K_XL (a 14.5 GiB knife-edge) and 12GB is 8K-only (smallest build 9.7 GiB at 8K). Above it, an RTX 5090 32GB reaches UD_Q6_K_XL; nice, not necessary. |
| Why it fits — and why not less | MoE saves compute, not memory: all 30.5B parameters (17.3 GiB at Q4_K_M) must sit in VRAM whatever the active count, and the KV rides a 3.0 GiB reported figure at 32K. The 3.3B-active design buys tok/s; the GB bill stays a 30B-class bill. |
⚠ Tight is a site-wide threshold: under 2.5 GiB of headroom against usable VRAM. Q4_K_M @32K leaves 1.7 GiB on a 24GB card — tight by the rule, comfortable in practice. The densest fit Q4_1 totals 21.4 GiB (1.1 to spare). Just past the line: Q5_K_S totals 23.1 GiB — 0.6 GiB over the 22.5 GiB usable; at 8K context it fits (20.9 GiB), and the GPU ladder prices that.
Tracked builds (actual file sizes, not theory)
| Build | Publisher | File size | 24GB @32K | Source |
|---|---|---|---|---|
| UD_IQ1_S | unsloth | 8.4 GiB | OK · 11.9 | HF @d5b1d57b verified |
| UD_Q2_K_XL | unsloth | 11.0 GiB | OK · 14.5 | HF @d5b1d57b verified |
| Q4_K_M | ggml-org | 17.3 GiB | TIGHT · 20.8 | HF @5e715e48 verified |
| Q4_1 | unsloth | 17.9 GiB | TIGHT · 21.4 | HF @d5b1d57b verified |
| UD_Q6_K_XL | unsloth | 24.5 GiB | NO · 28.0 | HF @d5b1d57b verified |
| Q8_0 | ggml-org | 30.3 GiB | NO · 33.7 | HF @5e715e48 verified |
Same quant, different builds — the mirror case for this model: unsloth and ggml-org ship the same-size Q4_K_M (18,556,686,912 vs 18,556,686,240 bytes — a 672-byte metadata difference on 18.56 GB) and the same-size Q8_0, so one row stands for each; there is no >5% same-name spread to split. The unsloth ladder still aims at the fixed tiers: UD_Q6_K_XL totals 28.0 GiB against 30.0 GiB usable on a 32GB card — a designed marginal fit (unsloth model card, linked, reported). Where 24GB ends at 32K: Q4_1 at 21.4 GiB; Q5_K_S (23.1 GiB) is the first door that misses; Q8_0 (33.7 GiB) needs 48GB-class.
Self-host or API?
Why in / out? Output tokens cost more than input: a prompt is read in one parallel pass, while output is generated token-by-token — costlier to serve. For example, qwen3-30b-a3b listed at $0.12 in / $0.50 out per 1M tokens in the 2026-09-18 OpenRouter snapshot; blended at a typical chat mix (4 input : 1 output) ≈ $0.20/1M.
API prices float; the crossover moves less than one decade either way — so this page answers the question that doesn't need live prices: how much monthly usage makes self-hosting worth considering at all.
| Monthly usage | Verdict | Why |
|---|---|---|
| < 30M tokens | API | Even the cheapest self-host ($30/mo) never breaks even against the API bill at this usage — don't bother calculating. |
| 30M-300M tokens | Conditional | The decisive variable is whether you already own a 24GB card — amortization dominates the self-host bill. |
| > 300M tokens | Self-host | Per-token API billing stops scaling here; consider a managed dedicated instance too — at 1B+ tokens/mo it often beats DIY. |
Robustness: at 0.10/1M blended the crossover sits near 600 tokens/mo; at 0.20/1M near 150/mo. The three bands hold under ±2.5× API-price and ±2× self-host-cost floats. Self-host cost basis: $800-1900 GPU amortized over 30 months ($27-63/mo) + ~350W × 4h/day × $0.15/kWh (≈ $6/mo). Live prices via OpenRouter (linked, not re-verified by us); the band is a 30B-class reference, not a pinned price for this model.
Where every number comes from (every figure carries its tag)
Totals: measured weights + reported KV (community measurement, linked) + measured overhead — labeled, additive. This page exists for one config: the 30B-class small-MoE agent tier × Q4_K-class quant × 32K context on a 24GB card — where MoE compute efficiency meets the fixed GPU tiers quant studios build around.
| Tag | Slot | What it is | What the verdict can claim |
|---|---|---|---|
| reported | model | Hugging Face config.json (hypothesis-parameter carrier) | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | static | Hugging Face model page | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | kv | KV cache @ 32K — kaitchup measured writeup: 'At 32k context, batch/concurrency = 1, that is about 3.22 GB (or 3.0 GiB)' (48 GQA layers × 4 KV heads × 128 head dim × 2 bytes × 2, bf16) | Tight, conditional — stands on the linked source, re-checkable by you. |
| measured | overhead | Deployment overhead — llama.cpp FA-on compute buffer anchor (507 MiB; measured empirical; same constant as the other champion pages) | Determinate — "it runs" means it runs. |
| Hugging Face config.json (hypothesis-parameter carrier) | @ad44e777 | accessed 2026-09-14 |
| Hugging Face model page | @ad44e777 | accessed 2026-09-14 |
| KV cache @ 32K — kaitchup measured writeup: 'At 32k context, batch/concurrency = 1, that is about 3.22 GB (or 3.0 GiB)' (48 GQA layers × 4 KV heads × 128 head dim × 2 bytes × 2, bf16) | latest | accessed 2026-09-05 |
| Deployment overhead — llama.cpp FA-on compute buffer anchor (507 MiB; measured empirical; same constant as the other champion pages) | latest | accessed 2026-09-05 |
FAQ
Should I use the standard Qwen3-30B-A3B or the Qwen3-Coder-30B-A3B for programming?
Same hardware, different training — the Coder page answers the same numbers this one does. Both are the 30.5B-A3B MoE with the same-size GGUF ladder (Q4_K_M totals 20.8 GiB at 32K context on either page; the two unsloth repos measure within 0.1 GiB of each other, and the official FP8 repos differ — 30.2 vs 29.0 GiB of weights). Download the Coder for IDE, agentic, and repo-scale coding: its post-training is code-specialized and its native context is 256K (this model's config stops at 40K, YaRN to 131K). Keep the standard for general chat and mixed workloads — it is the default the ollama short form (qwen3:30b) pulls.
Does Qwen3-30B-A3B fit in 24GB VRAM?
Yes, tight. The Q4_K_M build totals 20.8 GiB at 32K context against 22.5 GiB usable on an RTX 3090 24GB or 4090 24GB — 1.7 GiB to spare, under the site's 2.5 GiB tight threshold but a stable fit. The densest build that fits is Q4_1 at 21.4 GiB (1.1 GiB to spare).
It's a MoE with only 3.3B active parameters — does it need less VRAM?
No — activation is not residency. Every token touches only 3.3B of the 30.5B parameters (8 of 128 experts), which is what makes the MoE fast; but all 30.5B parameters must sit in VRAM for any of it to work. Weights alone are 17.3 GiB at Q4_K_M — a 30B-class memory bill with a 3B-class compute bill. VRAM follows total parameters, always.
How much VRAM does Qwen3-30B-A3B need at Q4_K_M?
20.8 GiB at 32K context: 17.3 GiB weights + 0.5 GiB runtime overhead + 3.0 GiB KV cache. The KV figure is reported (kaitchup: 'about 3.22 GB (or 3.0 GiB)' at 32K context, batch 1 — 48 GQA layers × 4 KV heads × 128 head dim, bf16). At 4K context the KV term shrinks eightfold to ≈0.4 GiB, so the same build runs in ≈18.2 GiB. The short form (ollama run qwen3:30b) pulls the ollama Q4_K_M build.
What is the smallest GPU that runs Qwen3-30B-A3B?
At 32K context an RTX 3060 12GB tops out at nothing — the smallest build totals 11.9 GiB against 10.5 GiB usable. At 8K context that build (UD_IQ1_S, 9.7 GiB) fits, tight. A 16GB card reaches UD_Q2_K_XL at 32K: 14.5 GiB against 14.5 GiB usable — a knife-edge fit, real but with zero headroom. Q4_K_M needs a 24GB card.
Can Qwen3-30B-A3B run above Q4 on a 24GB card?
Not at 32K: Q5_K_S totals 23.1 GiB, 0.6 GiB over the 22.5 GiB usable — at 8K context it fits (20.9 GiB), and the GPU ladder prices that. The 24GB ceiling at 32K is Q4_1 (21.4 GiB). An RTX 5090 32GB reaches UD_Q6_K_XL at 28.0 GiB; Q8_0 (33.7 GiB) needs 48GB-class hardware.
Which Q4 should I pick — unsloth or ggml-org?
For this model it doesn't matter by size: the two Q4_K_M builds differ by 672 bytes out of 18.56 GB (18,556,686,912 vs 18,556,686,240 B) — same-size mirror builds, so one row stands for both in the table above, and the same is true of Q8_0. That is the honest mirror case: no >5% same-name spread exists here, unlike the Qwen3.6-27B page's ggml-org Q4_K_M, which runs 13.4% larger.
How does this site compute these VRAM numbers?
Weights are measured file sizes at pinned revisions (sources below); totals add runtime overhead plus the KV cache at 32K context. Here KV@32K = 3.0 GiB, a reported measurement (98,304 B/token: 48 layers × 4 KV heads), linked in sources. A build fits a card at 32K when the total clears usable VRAM (nominal minus reserve), and tight means under 2.5 GiB of headroom — the full formula lives in the method box under the quantization table.