Qwen3.6-35B-A3B VRAM requirements
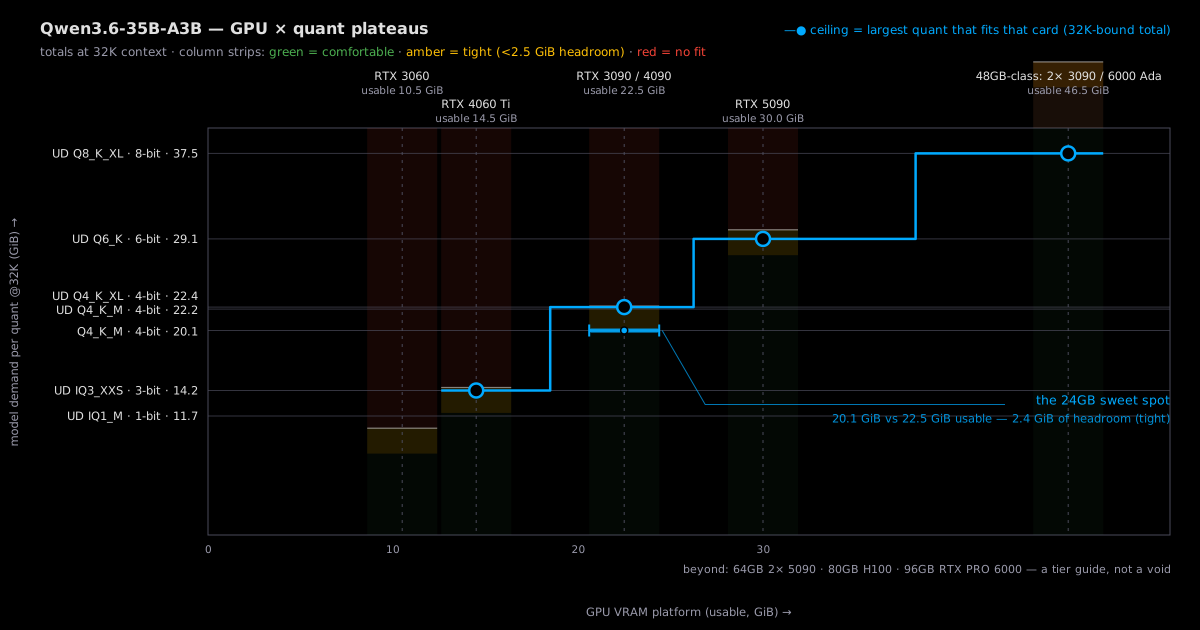
fits a 24GB card, tight — 2.4 GiB to spare · build choice matters: unsloth UD-Q4_K_M (MTP) totals 22.2, 0.3 to spare
The ggml-org Q4_K_M measures 19.02 GiB and totals 20.1 GiB at 32K context: any 24GB card runs it with 2.4 GiB to spare — tight by this site's 2.5 GiB threshold, because the 30 linear-attention layers keep the KV bill tiny (0.625 GiB config-derived; only the 10 GQA layers grow per token). Build choice moves the verdict: unsloth's MTP-including UD-Q4_K_M (21.11 GiB) totals 22.2, the densest fit UD-Q4_K_XL totals 22.4, and NVIDIA's own NVFP4 build (22.9) misses 24GB at 32K entirely. On a 12GB card the tracked ladder has no real door — unsloth's non-MTP IQ1_M knife-edges 32K at 0.02 GiB spare (not a door by this site's rule), so the reported route is Strata's hybrid mode (22-37 of 256 experts in VRAM); its docs state the Mac engine does not run this model.
Qwen3.6-35B-A3B-Q4_K_M.gguf from ggml-org (pinned, 19.02 GiB) and load it in llama.cpp or LM Studio — fits a 24GB card at full 32K context. For image or video input add the mmproj pack (0.84 GiB BF16) from the same repo; it still leaves room beside the hero build (2.4 GiB spare covers it). For speculative decoding, unsloth's MTP builds are the ones with the draft layer compiled in (see the MTP question below).Qwen3.6-35B-A3B is Alibaba's hybrid MoE: 35.9B parameters, 3.0B active per token, 256 experts (8 active + 1 shared), 40 layers = 30 GatedDeltaNet linear-attention + 10 full-attention GQA (config.json: 16 query heads, 2 KV heads, head dim 256), one MTP draft layer, vocab 248,320, embeddings untied. VRAM follows total parameters, not active ones — every expert stays resident. KV cache at 32K is 0.625 GiB, config-derived (20,480 bytes/token on the 10 GQA layers; the 30 GDN layers hold a constant recurrent state, disclosed below page rounding), provisional until a community measurement lands. Multimodal: a 27-layer ViT handles image and video input — the mmproj projection (0.84 GiB BF16) ships as a separate auxiliary file, excluded from every weight sum on this page. Native context 262,144 tokens (1,010,000 extensible is the HF model card's reported claim). Released 2026-04-16 under Apache-2.0; ≈3.6M downloads on Hugging Face as of the October 2026 snapshot (magnitude-only caliber).
Data verified · sources pinned in Where every number comes from
How much VRAM at each quantization? (weights + overhead + 4K KV, batch 1)
| Quantization | VRAM needed @4K | KV @32K provisional i · beyond the @4K column | Smallest tracked fit | Note |
|---|---|---|---|---|
| UD_IQ1_M | 11.2 GiB | 0.625 GiB | RTX 4060 Ti 16GB | measured weights · at 32K incl. KV: 11.7 GiB |
| UD_IQ3_XXS | 13.7 GiB | 0.625 GiB | RTX 4060 Ti 16GB | measured weights · at 32K incl. KV: 14.2 GiB |
| Q4_K_M | 19.6 GiB | 0.625 GiB | RTX 3090 24GB | measured weights · at 32K incl. KV: 20.1 GiB |
| UD_Q4_K_M | 21.7 GiB | 0.625 GiB | RTX 3090 24GB | measured weights · at 32K incl. KV: 22.2 GiB |
| UD_Q4_K_XL | 21.9 GiB | 0.625 GiB | RTX 3090 24GB | measured weights · at 32K incl. KV: 22.4 GiB |
| UD_Q6_K | 28.5 GiB | 0.625 GiB | RTX 5090 32GB | measured weights · at 32K incl. KV: 29.1 GiB |
| UD_Q8_K_XL | 37.0 GiB | 0.625 GiB | — | measured weights · at 32K incl. KV: 37.5 GiB |
GB vs GiB: card names are the manufacturer's nominal GB; totals here are GiB (230 bytes) — a "24GB" card holds 24 GiB, and the ggml-org Q4_K_M quoted as a 20.4 GB download is the same 19.0 GiB file (decimal vs binary). Caliber →
The 48GB-class doors, spelled out: a dual-GPU combo (2× 24GB; not one card doubled), a workstation card (RTX 6000 Ada), or an Apple-Silicon Mac via unified memory (llama.cpp-class runtimes load the GGUF builds; slower tok/s). For this model they open every build through UD_Q8_K_XL (37.5 GiB) — including Q8_0 at 35.5 — while the BF16 original (68.1 GiB at 32K) needs 96GB-class unified memory. Note the Strata engine's Mac build explicitly does not run this model (reported, linked in sources) — on macOS it's the plain GGUF route or nothing.
How this page computes the numbers (reproduce any cell)
- usable VRAM = nominal minus reserve, per card: 12GB → 10.5 GiB, 16GB → 14.5 GiB, 24GB → 22.5 GiB, 32GB → 30.0 GiB.
- total@32K = weights + overhead + KV@32K; KV@32K = 0.625 GiB (config-derived — 20,480 B/token effective at 32K; hybrid models carry a constant state on top, composition in sources).
- total@4K (main column) = total@32K − KV@32K × 7/8 — KV is fully linear in context on this model.
- The "≤~XK ctx" note = 8K + 32K × (usable − total@8K) ÷ KV@32K — the context length that exactly fills the card (KV grows linearly with context on this model).
- A build fits a card at 32K when total@32K ≤ usable; tight = under 2.5 GiB of headroom, one site-wide threshold.
Is your GPU enough? (find your card: one row tells you)
| Your GPU | VRAM | Biggest quant that fits (ceiling) | How it feels |
|---|---|---|---|
| RTX 3060 12GB | 12 GB | — | — |
| RTX 4060 Ti 16GB | 16 GB | UD_IQ3_XXS (3-bit) · 14.2 GiB | 0.3 GiB spare at 32K (incl KV bound) |
| RTX 3090 24GB | 24 GB | UD_Q4_K_XL (4-bit) · 22.4 GiB | 0.1 GiB spare at 32K (incl KV bound) |
| RTX 4090 24GB | 24 GB | UD_Q4_K_XL (4-bit) · 22.4 GiB | 0.1 GiB spare at 32K (incl KV bound) |
| RTX 5090 32GB | 32 GB | UD_Q6_K (6-bit) · 29.1 GiB | 0.9 GiB spare at 32K (incl KV bound) |
Quants stack by size: each GPU has exactly one ceiling — a card that runs a bigger build runs every smaller one. Main-column totals price the 4K load (weights + overhead + the 4K KV term); each row's Note prices the full 32K load this page promises (20.1 GiB at Q4_K_M); and CPU-offload engines (Strata's hybrid mode, reported) trade tok/s for headroom on cards the plain ladder gives nothing — the 12GB question above.
What GPU should you buy for it? (the 24GB sweet spot logic)
| The logic | 24GB is the tier that runs Q4_K_M at the full 32K window this page promises: 20.1 GiB all-in against 22.5 GiB usable — 2.4 GiB spare, "tight" by this site's 2.5 GiB rule, and it holds. Below it: 16GB tops out at UD_IQ3_XXS (a 14.2 GiB knife-edge), and 12GB has no plain-fit door at all (smallest enumerated build 11.7 GiB). Above it: a 32GB card reaches UD_Q6_K (29.1 GiB, 0.9 GiB spare — tight); nice, not necessary — 24GB already runs the sweet-spot quant. |
| Why it fits — and why not less | MoE saves compute, not memory: all 35.9B parameters (19.0 GiB at Q4_K_M) must sit in VRAM whatever the active count, and the hybrid KV bill rides a config-derived 0.625 GiB at 32K because only 10 of 40 layers grow per token. The 3.0B-active design buys tok/s; the GB bill stays a 36B-class bill. And build choice is the difference between 2.4 GiB of headroom (ggml-org Q4_K_M) and 0.3 (unsloth's MTP UD-Q4_K_M): same card, same quant name, different file. |
⚠ Tight is a site-wide threshold: under 2.5 GiB of headroom against usable VRAM. This page's 24GB story is a tight-band stack: Q4_K_M @32K leaves 2.4 GiB (tight — the hero), UD-Q4_K_M (MTP) leaves 0.3, and the densest fit UD_Q4_K_XL leaves 0.1. Just past the line: UD-Q5_K_S totals 24.9 GiB — 2.4 GiB over the 22.5 GiB usable; and NVIDIA's own NVFP4 build totals 22.9 GiB, missing by 0.4 (at 8K it fits by 0.03 — a knife-edge, not a door). All totals carry the config-derived KV, so these verdicts move only if a measured-KV revision lands — the knife-edge cells (0.03/0.1/0.3 spare) are the ones to watch.
Tracked builds (actual file sizes, not theory)
| Build | Publisher | File size | 24GB @32K | Source |
|---|---|---|---|---|
| UD_IQ1_M | unsloth | 10.6 GiB | OK · 11.7 | HF @5bc3e238 verified |
| UD_IQ3_XXS | unsloth | 13.1 GiB | OK · 14.2 | HF @5bc3e238 verified |
| Q4_K_M | ggml-org | 19.0 GiB | TIGHT · 20.1 | HF @7878dc9a verified |
| UD_Q4_K_M | unsloth | 21.1 GiB | TIGHT · 22.2 | HF @5bc3e238 verified |
| UD_Q4_K_XL | unsloth | 21.3 GiB | TIGHT · 22.4 | HF @5bc3e238 verified |
| Q6_K | lmstudio-community | 26.6 GiB | NO · 27.7 | HF @68a34855 verified |
| UD_Q6_K | unsloth | 28.0 GiB | NO · 29.1 | HF @5bc3e238 verified |
| Q8_0 | ggml-org | 34.4 GiB | NO · 35.5 | HF @7878dc9a verified |
| NVFP4 | nvidia | 21.8 GiB | NO · 22.9 | HF @1355db6a verified |
| BF16 | Qwen | 67.0 GiB | NO · 68.1 | HF @995ad96e verified |
Same quant name, different builds — this model's signature: unsloth ships two repos, the MTP-GGUF (multi-token-prediction draft layer compiled in) and the plain GGUF, and the MTP layer adds ≈0.4-1.6 GiB per file (UD-Q4_K_XL: 21.28 vs 20.82; UD-Q6_K: 27.95 vs 27.30; Q8_0: 35.21 vs 34.37). The Strata engine pulls the MTP builds. ggml-org's Q4_K_M (19.02 GiB) is the smallest Q4_K_M in our sources — lmstudio's measures 19.71 (3.6% over, same-name mirror band) and both unsloth UD-Q4_K_M builds are bigger still (different tensor coverage). NVIDIA's official NVFP4 safetensors (21.82 GiB, 3 shards) is the vLLM-ready modelopt form (pinned README lists Hopper and Blackwell hardware). The vision tower is in none of these files: it ships as a separate mmproj pack (0.84 GiB BF16), loaded only when an image or video arrives; ggml-org's mtp-* and dflash-* sidecars are excluded from every weight sum. A supply correction from the October 20 review pass: bartowski does publish — a full GGUF ladder at Qwen_Qwen3.6-35B-A3B-GGUF (underscore naming our first probes missed; 36 files, ≈180K downloads), including an IQ1_M whose 32K total works out to ≈9.9 GiB (≈0.6 GiB spare on a 12GB card — the first real 1-bit door, intake pending, not yet in the tables above) — and ISTA-DASLab publishes a 2-bit GSQ safetensors quant. Neither is in the tracked tables yet. ≈3.6M HF downloads, October 2026 snapshot (magnitude only).
Self-host or API?
API prices are sourced from OpenRouter (linked, not re-verified). We have not pinned a price for Qwen3.6-35B-A3B, so the breakeven cell stays empty rather than guessing. When a price is pinned, this block compares API cost per million tokens against self-hosting on your own card — the 24GB card this page prices is the cheapest credible self-host seat for a 35B-class MoE.
Where every number comes from (every figure carries its tag)
Totals: measured weights + KV as the config-derived hybrid figure (20,480 B/token on the 10 full-attention layers; 30 GatedDeltaNet layers hold a constant state, disclosed) + measured overhead. This page exists for one config: the 35B-class hybrid MoE × Q4_K_M × 32K context on a 24GB card — where linear-attention KV thrift meets the fixed GPU tiers quant studios build around.
| Tag | Slot | What it is | What the verdict can claim |
|---|---|---|---|
| reported | model | Hugging Face config.json (identity carrier; qwen3_5_moe: 40 layers = 30 GatedDeltaNet + 10 full GQA per layer_types, full_attention_interval=4, 256 experts top-8+1 shared, head_dim 256, vocab 248,320, MTP layer 1, vision_config 27-layer ViT, mamba_ssm_dtype=float32) | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | static | HF model page (Qwen/Qwen3.6-35B-A3B) — license apache-2.0, pipeline_tag image-text-to-text, createdAt 2026-04-15 | Tight, conditional — stands on the linked source, re-checkable by you. |
| provisional | kv | KV cache @ 32K — no published measurement in our sources; config-derived: 0.625 GiB = 20,480 B/token × 32768 on the 10 full-attention GQA layers only (2 KV heads × 256 dim × 2(K,V) × 2 B), provisional; the 30 GatedDeltaNet layers hold a constant recurrent state (~0.03 GiB config-derived / 0.07 GB per Strata's doc, below page rounding, excluded and disclosed); Strata's fp32 note '≈45 KB/token' is same-order corroboration | Very likely right, order of magnitude only — replaced the moment measured values land. |
| measured | overhead | Deployment overhead — llama.cpp FA-on compute buffer anchor (≈0.5 GiB; measured empirical; same constant as the other champion pages) | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (Qwen/Qwen3.6-35B-A3B) — official BF16 safetensors, 26 shards summed (vision tower included in-repo; text-inference sums exclude the mmproj auxiliary per site convention); pinned | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (ggml-org/Qwen3.6-35B-A3B-GGUF) — canonical Q4_K_M 19.02 GiB single file + Q8_0 + BF16 (mtp/dflash/mmproj sidecars excluded from weight sums); pinned | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (unsloth/Qwen3.6-35B-A3B-MTP-GGUF) — MTP-inclusive ladder (UD-Q4_K_XL/UD-Q6_K/Q8_0/UD-Q8_K_XL + IQ/Q3-Q5 family; mmproj/imatrix excluded); the builds the Strata engine pulls; pinned | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (unsloth/Qwen3.6-35B-A3B-GGUF) — non-MTP ladder of the same quants (0.5-2 GiB smaller per file: no draft layer); same quant name ≠ same build; pinned | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (lmstudio-community/Qwen3.6-35B-A3B-GGUF) — Q4_K_M 19.71 / Q6_K 26.56 / Q8_0 34.37 GiB; pinned | Determinate — "it runs" means it runs. |
| measured | static | HF repo tree (nvidia/Qwen3.6-35B-A3B-NVFP4) — official NVFP4 safetensors, 3 shards summed (vLLM-ready modelopt 4-bit; pinned README lists Hopper and Blackwell hardware); pinned | Determinate — "it runs" means it runs. |
| reported | static | Qwen model card (pinned README) — 262,144 native context (1,010,000 extensible = reported claim), image+video input via the vision encoder, Apache-2.0, snapshot counters ≈3.6M downloads / 3,010 likes as of 2026-10-20 (magnitude-only caliber) | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | static | llm-stats.com model page — 'released on April 16, 2026 by Qwen' (release-date evidence #2; HF lastModified 2026-04-24 is a post-release refresh, not the release) | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | static | Strata engine doc docs/QWEN36.md (Niko1221/Strata, pinned) — reported engine claims only: src/qwen35 engine path, unsloth MTP GGUFs (UD-Q4_K_XL/UD-Q6_K_XL/Q8_0), RTX 3060 12GB hybrid mode 22-37/256 experts in VRAM, R9700 32GB full-VRAM decode 117.8 tok/s (0.1.45), parallel serving up to 8 slots, 'The Mac engine does not run this model.' | Tight, conditional — stands on the linked source, re-checkable by you. |
| reported | static | Supply correction (2026-10-20 post-review, supersedes the same-day negative row): the original name probes used dash naming (bartowski/Qwen3.6-35B-A3B-GGUF, ISTA-DASLab/Qwen3.6-35B-A3B-GGUF) and their authed 404s were real — but both publishers publish under different names. bartowski ships a full GGUF ladder at bartowski/Qwen_Qwen3.6-35B-A3B-GGUF (36 files, ≈180K downloads; IQ1_M 8.78 GiB, Q4_K_M 20.75 GiB — authed probe 200, body saved) and ISTA-DASLab ships a 2-bit GSQ safetensors quant (ISTA-DASLab/Qwen3.6-35B-A3B-2Bit-GSQ, 55 files, authed 200). Neither is yet in the tracked tables (intake pending); the bartowski IQ1_M totals ≈9.9 GiB at 32K and fits a 12GB card with ≈0.6 GiB spare — the first real 1-bit door once intaken. | Tight, conditional — stands on the linked source, re-checkable by you. |
FAQ
Does Qwen3.6-35B-A3B fit in 24GB VRAM?
Yes, tight — and the build choice decides by how much. The ggml-org Q4_K_M (the official llama.cpp-org build) totals 20.1 GiB at 32K context: 19.02 GiB weights + ≈0.5 GiB runtime overhead + 0.625 GiB config-derived KV, leaving 2.4 GiB of a 24GB card's 22.5 GiB usable — under this site's 2.5 GiB tight threshold. The unsloth UD-Q4_K_M (MTP build) weighs 21.11 GiB and totals 22.2 — only 0.3 GiB to spare. The densest fit is unsloth's UD-Q4_K_XL at 22.4 GiB (0.1 to spare). NVIDIA's own NVFP4 build does not fit at 32K: 22.9 GiB all-in misses usable by 0.4 GiB (at 8K context it totals 22.47 GiB — a knife-edge that fits by 0.03). Above Q4 nothing fits 24GB at 32K: UD-Q5_K_S already totals 24.9 GiB, 2.4 GiB over usable.
What is the smallest GPU that runs Qwen3.6-35B-A3B?
16GB is the smallest sane tier: at 32K context an RTX 4060 Ti 16GB tops out at UD-IQ3_XXS (14.2 GiB all-in, 0.3 GiB to spare) — no 4-bit build fits 16GB (UD-IQ4_XS totals 18.1). At 8K context the picture barely changes: the KV term shrinks to ≈0.16 GiB, and UD-IQ3_XXS drops to 13.7. A 12GB card has no ceiling on the builds this page enumerates: the smallest of them (UD-IQ1_M, the 1-bit MTP build at 10.59 GiB of weights) totals 11.7 GiB at 32K and 11.2 GiB at 8K — both over the 10.5 GiB usable on an RTX 3060 12GB. The cheapest tracked file overall is the non-MTP unsloth UD-IQ1_M at 9.36 GiB (pinned, in the builds table sources): at 8K context that file totals ≈10.0 GiB and fits a 12GB card, tight; at 32K it is a 0.02-GiB knife-edge — arithmetically inside, practically pinned to the metal, and this page does not recommend it as a real 12GB door. For a real 12GB route see the Strata engine question below (reported hybrid mode).
It's a MoE with only 3.0B active parameters — does it need less VRAM?
No — activation is not residency. Every token touches only 3.0B of the 35.9B parameters (8 of 256 experts, plus 1 shared), which is what makes the MoE fast; but all 35.9B parameters must sit in VRAM for any of it to work. Weights alone are 19.0 GiB at Q4_K_M — a 36B-class memory bill with a 3B-class compute bill. VRAM follows total parameters, always. (This is the same rule the predecessor Qwen3-30B-A3B page states for its 30.5B/3.3B split.)
How much VRAM does Qwen3.6-35B-A3B need at Q4_K_M?
20.1 GiB at 32K context: 19.02 GiB weights + ≈0.5 GiB runtime overhead + 0.625 GiB KV cache. The KV figure is config-derived, not a community measurement: 20,480 bytes/token × 32K, counting only the 10 full-attention GQA layers (2 KV heads × 256 head dim, bf16) — the 30 GatedDeltaNet layers hold a constant recurrent state instead of per-token KV, so the hybrid bill grows ~4.8× slower per context token than the all-attention predecessor. Context scaling at Q4_K_M: ≈19.6 GiB at 4K, 19.7 at 8K, 22.0 at 128K (still inside a 24GB card, tight), and ≈24.5 at the full 262,144 — past usable, so the full native window needs a 32GB card. Strata's doc states the same shape in fp32 ('≈45 KB/token' for the 10 attention layers plus the MTP block).
MTP vs non-MTP GGUF builds — which do I download?
Same quant name, two different files. unsloth ships two repos: Qwen3.6-35B-A3B-MTP-GGUF (with the multi-token-prediction draft layer compiled in, for speculative decoding) and Qwen3.6-35B-A3B-GGUF (without). The MTP layer adds ≈0.4-1.6 GiB per file: UD-Q4_K_XL is 21.28 GiB with MTP vs 20.82 without, Q8_0 is 35.21 vs 34.37, UD-Q4_K_M is 21.11 vs 20.61. The Strata engine's dedicated qwen35 path pulls the MTP builds (reported, linked below); plain llama.cpp/Ollama/LM Studio runs don't need the draft layer — take the smaller non-MTP file unless your runtime does speculative decoding. ggml-org's repo instead ships the MTP weights as separate mtp-* sidecar files, which this site excludes from weight sums (same rule as mmproj vision packs).
Can the Strata engine really run this on a 12GB card?
Per Strata's own documentation — reported, we link it, we did not re-run it: yes, in hybrid mode. Strata's dedicated engine path (src/qwen35) loads the unsloth MTP builds (UD-Q4_K_XL / UD-Q6_K_XL / Q8_0) and, on an RTX 3060 12GB, keeps 22-37 of the 256 experts per layer in VRAM with the rest on CPU — a tiered door this site's plain-fit ladder doesn't price. On an R9700 32GB every expert stays in VRAM (decode 117.8 tok/s on 0.1.45, reported), and parallel serving runs up to 8 slots (R9700 8 requests: 325.4 tok/s aggregate vs llama.cpp's 208.1, reported). The honest half of the claim: 'The Mac engine does not run this model.' If you're on Apple Silicon, the plain GGUF builds via llama.cpp-class runtimes are the route — see the 48GB-class door note above. Engine home: Strata.
Qwen3.6-35B-A3B vs Qwen3.6-27B — same 24GB tier, which one?
Both are 24GB-tier Q4_K_M cards (the related row below prices the 27B; this page's hero is 20.1 GiB at 32K). The difference is how they spend the budget: the 27B is the dense sibling — every parameter works on every token; the 35B-A3B is a 256-expert MoE that touches only 3.0B parameters per token, which is where its decode speed comes from, at the cost of carrying 35.9B parameters resident. Same card runs either; the MoE buys tok/s, the dense model buys simplicity (no expert-routing behavior to reason about). This is a same-family comparison — the 27B page carries its own measured ladder.
How does Qwen3.6-35B-A3B compare to its predecessor Qwen3-30B-A3B?
The successor changes the architecture, not the card tier. The predecessor is 30.5B parameters (3.3B active) with 48 full-attention GQA layers — its KV bill is 98,304 B/token, a reported 3.0 GiB at 32K. This model is 35.9B (3.0B active) with only 10 full-attention layers among its 40 (30 GatedDeltaNet linear layers handle the rest), so its config-derived KV is 20,480 B/token = 0.625 GiB at 32K — the long-context bill grows ~4.8× slower. Both land in the same place for a buyer: Q4_K_M-class GGUF, ~20-21 GiB all-in, fits a 24GB card tight. Both natively span 262,144 tokens. The predecessor's page answers the same questions for the older architecture — linked in the related row below (and this page is linked back from it).
How does this site compute these VRAM numbers?
Weights are measured file sizes at pinned revisions (sources above); totals add runtime overhead (0.4951 GiB, the llama.cpp anchor used site-wide) plus the KV cache at 32K context. Here KV@32K = 0.625 GiB, config-derived: 20,480 B/token on the 10 full-attention layers (2 KV heads × 256 dim × 2 bytes × K,V), provisional until a community measurement lands — the derivation inputs live in the db and the method box under the quantization table. A build fits a card at 32K when the total clears usable VRAM (nominal minus reserve), and tight means under 2.5 GiB of headroom. The 30 GatedDeltaNet layers hold a constant recurrent state (~0.03 GiB config-derived) instead of per-token KV — disclosed, below page rounding, not counted.