DeepSeek-V4-Flash-0731 VRAM requirements
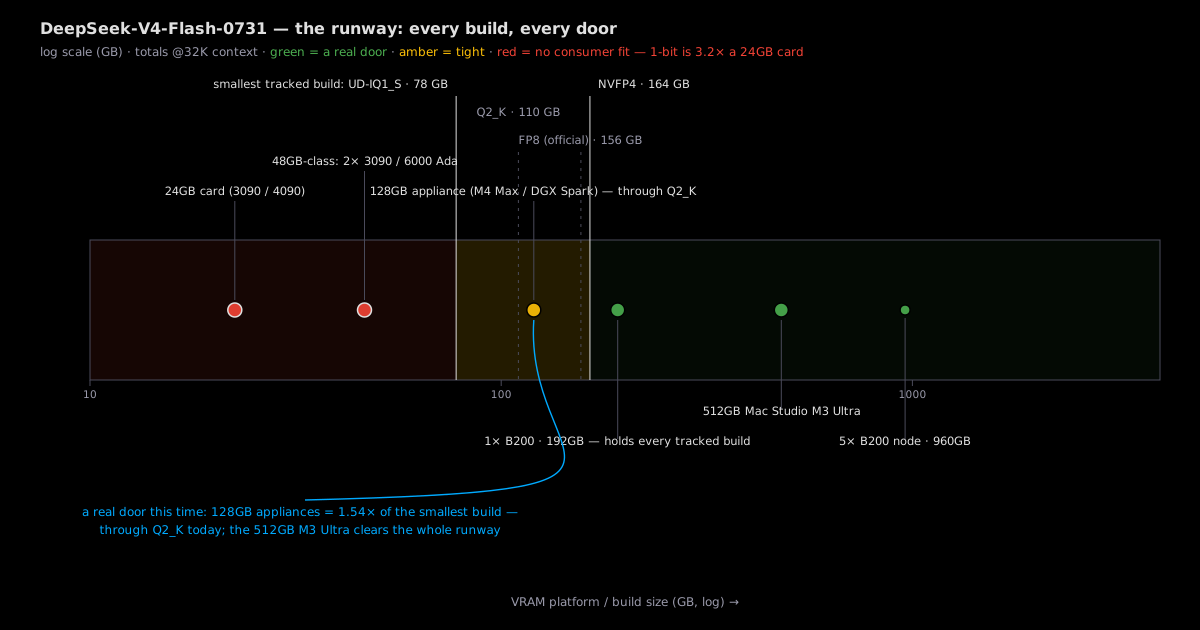
DeepSeek-V4-Flash-0731 is the July 31, 2026 refresh of DeepSeek-V4-Flash — same architecture plus the DSpark speculative-decoding module; its smallest measured build is unsloth's UD-IQ1_S, 1-bit. Three doors are real: every tracked build fits a single 192 GB B200 (1× at the smallest, 1× at NVFP4); a 512GB Mac Studio runs all of them; and a reported community path runs the 1-bit build on a 24GB card with 96GB of system RAM (offload, not VRAM). The official-precision FP8 build totals 156.2 GiB. Looking for the version-agnostic answer? The unversioned page tracks the current main version — as of September 2026 that is still the 0731 weights.
Updated · data status: MEASURED WEIGHTS — totals = measured weights + reported KV (source-published 1M figure, linear-rescaled down to 32K — over-counts at short context (the source's own note), direction: scaled down, not measured at 32K) + measured overhead; every weight is a pinned file-size sum (unsloth / ggml-org / bartowski / mlx-community / nvidia / deepseek-ai)
Rent it: minimal cloud configs (the smallest door in)
| Quantization | Total VRAM | Minimal single-node config | Verdict |
|---|---|---|---|
| UD-IQ1_S (measured) | 77.7 GiB | 1× B200 / 1× MI300X | EXTREME · 1-bit trade-off |
| UD-IQ2_XXS (measured) | 85.4 GiB | 1× B200 / 1× MI300X | EXTREME · 2-bit dynamic |
| UD-IQ4_NL (measured) | 128.1 GiB | 1× B200 / 1× MI300X | single-node door · cheapest Q4-named build (classify ratio 5.34×) |
| UD-Q4_K_XL (measured) | 145.2 GiB | 1× B200 / 1× MI300X | single-node door · the Q4_K_M-equivalent |
| FP8 (official deepseek-ai) | 156.2 GiB | 1× B200 / 1× MI300X | the official-precision door |
| NVFP4 (nvidia) | 164.3 GiB | 1× B200 / 1× MI300X | single-node door · NVIDIA format |
Card counts are plain division (rounded up) against published per-GPU memory (B200 192GB, MI300X 192GB) on measured totals — weights + a reported KV line + measured overhead. The KV line is arithmetic from the source's published 1M figure (reported, linked; the source's own note says it over-counts at short context), so totals are labeled provisional, not measured — at 3× of a 24GB card no consumer row is anywhere near the line, and that verdict doesn't move. Every door below is a single node.
Appliance / unified-memory form factors
| Appliance | Unified memory | Best fit | Verdict |
|---|---|---|---|
| Mac Studio M3 Ultra | 512 GB | every build through NVFP4 (164.3 GiB) fits — 6.24× of smallest (usable), a real door | FITS · 1-bit through NVFP4 |
| Mac Studio M4 Max | 128 GB | builds through Q2_K (110.1 GiB) fit — 1.56× of smallest | FITS · 1–2-bit + Q2 doors |
| NVIDIA DGX Spark | 128 GB | builds through Q2_K (110.1 GiB) fit — 1.56× of smallest | FITS · 1–2-bit + Q2 doors |
The appliance column is a real exit and a wide one: the 512GB Mac Studio (480 GiB usable) holds every tracked build through 164.3 GiB NVFP4 — 6.24× of the measured 76.9 GiB smallest file — and the 128GB boxes (120 GiB usable, 1.56×) clear the builds through the 110.1 GiB Q2_K door. Ratios compare usable memory to build file size, both figures in GiB (binary) — the division is computed and checked in a single unit end to end, so decimal-GB rereadings of these numbers do not apply; unified-memory bandwidth trails datacenter GPUs by an order of magnitude, so these are "it runs" verdicts, not "it runs fast".
Can't run it? The distill / step-down ladder
No official DeepSeek-V4-Flash-0731 distill is tracked in our sources yet. The model runs the same hybrid CSA / HCA attention as the base V4-Flash release (the successor of the V3-era MLA line; pinned sources below) and adds the DSpark draft module — llama.cpp merged support on August 2, 2026 (PR #25784, linked via sources); the PR's own DGX Spark bench shows roughly 50% faster decode, a wall-time win that does not lower the memory floor. A V4-Flash distill or step-down sibling would instantly become the family's consumer entry — a native small model beats a 1-bit 284B every time. When official distills or smaller siblings ship, each gets its own VRAM page and this section links the full ladder; until then, the smallest real door is the pinned 1-bit build in the rent table above.
Step-down options that exist: DeepSeek's own R1-Distill line from the V3 generation — R1 reasoning distilled into Qwen (1.5B/7B/14B/32B) and Llama (8B/70B) bodies, real files on Hugging Face (provenance below) — is the runnable DeepSeek-family answer while V4-Flash has no distill of its own; the V3 base generation itself is not yet tracked on this site. Version note: the unversioned deepseek-v4-flash page tracks whatever the current main version is — as of September 2026 that IS 0731, so the two pages price the same files; the difference is intent — this page answers versioned queries, that one answers "the current DeepSeek-V4-Flash". API note: since the V4.1-Flash release of September 10, 2026 the deepseek-v4-flash API name is retired and routes to the newer V4.1-Flash (current primary name: deepseek-flash) — the API name you call is no longer proof of which weights you get; these pages answer for the weights.
Private deployment (enterprises, labs, providers)
A separate query family from everything above: vLLM / SGLang tensor-parallel reference configs for the CSA/HCA stack, DSpark speculative-decoding deployments (llama.cpp PR #25784), compliance and air-gapped installs, TCO modeling against the API. The buyers here are not price-shopping: regulated workloads, data-residency rules, and air-gapped labs make self-hosting a procurement requirement, not an optimization. And the capacity fact flips the usual deploy math: a single B200 node already holds every tracked build, so the question is governance, not RAM.
Or just use the API
Honest take: DeepSeek-V4-Flash-0731 is a 284.0 B MoE with 13.0 B active parameters — the shape where hosted APIs are cheapest to run and hardest to beat on cost: 13B-active inference is exactly what API fleets optimize. Version note: since the V4.1-Flash release of September 10, 2026, the deepseek-v4-flash API name routes to the newer V4.1-Flash — check the provider's live model list for current names. Self-hosting makes sense when private deployment is the requirement, not to save money. Prices are linked, not pinned.
Where every number comes from (every figure carries its tag)
| Tag | Slot | What it is | What the verdict can claim |
|---|---|---|---|
| measured | Build file sizes | Community + official quant files, sizes summed at pinned revisions (unsloth / ggml-org / bartowski 0731 GGUF, mlx-community 2.4bit, nvidia NVFP4, deepseek-ai FP8 — linked below). | Determinate at each door — a platform above or below a measured file size is a fact, not an estimate. |
| provisional | Totals (weights + KV + overhead) | Simple addition: measured weights + reported KV (arithmetic from the source's published 1M bf16 total, linear-rescaled to 32K; the source's own note: it over-counts at short context, so read it as a short-ctx ceiling, not a measurement) + a measured overhead anchor (llama.cpp discussion #9936). | The KV line is a rounding-level term next to the weights — totals sit within about a GiB of the weights alone; at 3× of a 24GB card, no door verdict moves on this line. |
| provisional | Cloud card counts | Simple division against published per-GPU memory (B200 192GB, MI300X 192GB — linked below). | Card counts follow arithmetically once totals are set. |
| reported | Offload path (24GB card + 96GB RAM) | Single community source — tensorrigs hardware guide (accessed 2026-09-08, written for the same weight base), linked, not re-measured by us. | One self-declared "cheapest entry for 300B-class" route: weights live in system RAM, the GPU takes attention + active experts. A reported route, not a verified verdict. |
| reported | Release facts (0731 identity) | 0731 release facts — July 31 2026 ship date, MIT license, DSpark module — from the DeepSeek-V4-Flash-0731 release coverage (v4flash.com release notes + premai.io review, linked below). | Version identity claims track the linked pages, not our measurement. |
| reported | API prices | Referenced from OpenRouter, linked, not re-verified by us. | Tracks the linked page — prices move, we don't pin them. |
FAQ
What is DeepSeek-V4-Flash-0731 and how is it different from DeepSeek-V4-Flash?
0731 is the July 31, 2026 refresh of DeepSeek-V4-Flash: DeepSeek kept the size class (284B total, 13B active, 1M context) and shipped an agent/coding-focused update under MIT, adding a DSpark speculative-decoding module on the same hybrid CSA / HCA attention. Practically: the unversioned page and this one price the same files — the 0731 weights were still the newest DeepSeek-V4-Flash release on Hugging Face as of September 2026, and this page exists for the versioned-query audience ("did you mean the July build?"). API note: since the V4.1-Flash release of September 10, 2026, the deepseek-v4-flash API name is retired and routes to the newer V4.1-Flash — API routing and Hugging Face weights are now two different things; these two pages answer for the weights.
Can DeepSeek-V4-Flash-0731 run on an RTX 4090?
Not in VRAM — the smallest measured build (unsloth UD-IQ1_S) totals 77.7 GiB, 3× the card's 24GB. A reported community path runs the 1-bit build on a 24GB card with 96GB of system RAM (tensorrigs, linked — offload, at a fraction of datacenter speed). The in-VRAM paths are a single B200, a 512GB Mac Studio, or the API.
Can a 96GB workstation card (RTX PRO 6000 Blackwell) run DeepSeek-V4-Flash-0731?
At 32K context the smallest build's total (77.7 GiB) is 0.8× of the card's 96GB — it loads on paper. At the model's full 1M context the KV line grows to the source's published 1M figure (linked below), pushing the smallest build's total past the card's entire memory — no room left for activations and system: practically no. We promise order-of magnitude, not decimal-precision, on this edge.
How many GPUs do you need to run DeepSeek-V4-Flash-0731?
One, at every tracked build: even NVFP4 (164.3 GiB) fits a single 192GB B200 (card counts are plain division on measured totals). A 5× B200 node is a throughput choice, not a capacity requirement.
Can a Mac Studio run DeepSeek-V4-Flash-0731?
Yes — and unusually widely. The 512GB M3 Ultra (480 GiB usable) runs every tracked build through the 164.3 GiB NVFP4; the 128GB boxes (M4 Max / DGX Spark, ~120 GiB usable) run the builds through the 110.1 GiB Q2_K door. Unified-memory bandwidth caps throughput, so treat these as "it runs" verdicts.
Is there a smaller version of DeepSeek-V4-Flash-0731?
No official distill is tracked in our sources yet. The model runs the family's hybrid CSA / HCA attention plus the DSpark draft module (llama.cpp support merged August 2, 2026, PR #25784 — about 50% faster decode on the PR's own DGX Spark bench; a wall-time win, not a lower memory floor). When a V4-Flash distill or smaller sibling ships it becomes the practical consumer entry, and this page will link it.
Can I run DeepSeek-V4-Flash-0731 in Ollama?
Not locally from the official library — Ollama's official listing is cloud-only (the :cloud tags; Ollama hosts it, no local weights are offered). A community import exists (frob/deepseek-v4-flash-0731 — unsloth's 0731 GGUF re-listed; needs Ollama v0.31.1+). The well-trodden local doors skip Ollama entirely: llama.cpp mainline (DSpark support merged August 2, 2026 — PR #25784), LM Studio, and Unsloth Studio load the tracked builds directly; the tight-machine recipes in the community (1-bit build, KV-cache flags, layer offload) are llama.cpp-ecosystem recipes.
Why does ggml-org ship DeepSeek-V4-Flash-0731 as MXFP4 instead of a Q4_K_M like unsloth?
MXFP4 is a native low-precision floating-point format — 4-bit floats with a shared scale per block — designed for hardware that executes it directly (NVIDIA Blackwell-generation tensor cores and newer), while Q4_K_M is a GGUF integer k-quant: 4-bit integers stored with scale tables and dequantized before each matmul. The choice is about the format, not the file size — the format determines accuracy per bit, speed on a given chip, and which hardware runs it natively, and the ~144 GiB is just where those choices land, which is why ggml-org's MXFP4 build and unsloth's Q4_K_M-equivalent UD-Q4_K_XL end up within a fraction of a GiB of each other (pinned sources below).